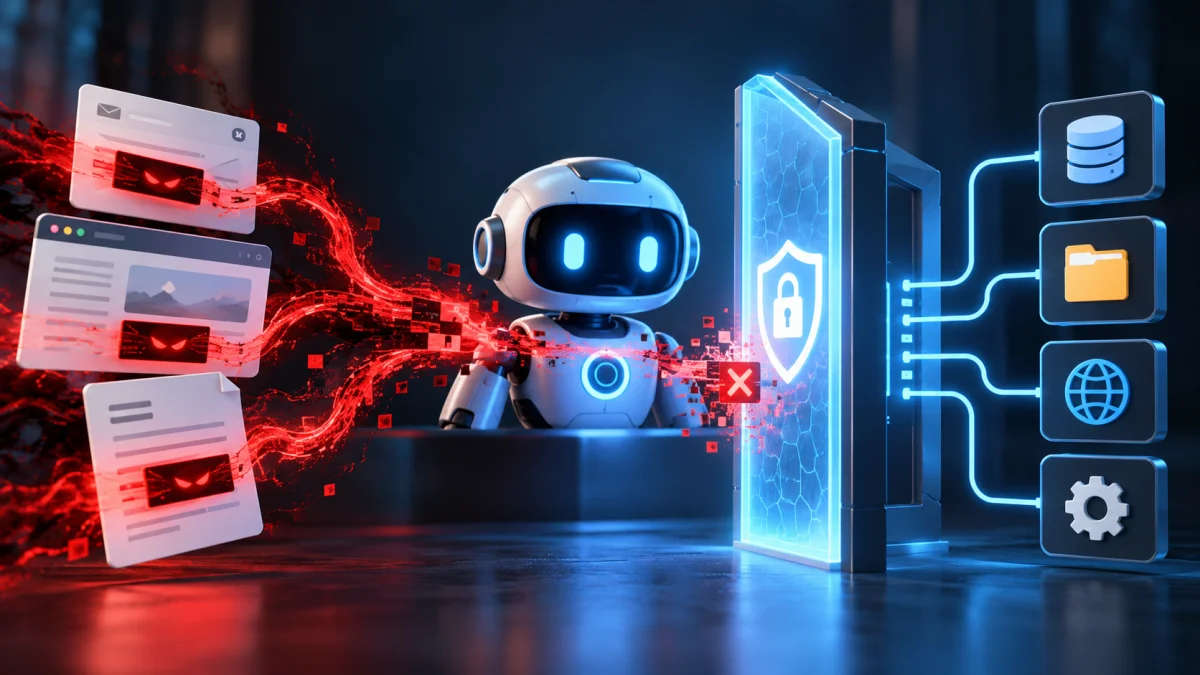
Prompt injection cannot be made harmless by writing a stronger system prompt. For a tool-using AI agent, the safer assumption is that untrusted content may eventually influence the model. The practical defense is therefore architectural: limit what the agent can access, put authorization and parameter checks at the tool boundary, require independent approval for consequential actions, isolate execution, control memory writes, and monitor what the agent actually does.
This changes the security goal. Instead of trying to guarantee that the model will never follow a malicious instruction, design the system so that a successful injection has limited authority, limited persistence and an observable audit trail.
Prompt injection becomes more dangerous when agents can act
OWASP defines prompt injection as malicious instructions in model input that redirect the model away from the application’s intended behavior. A chatbot that can only produce text may return a bad answer. An agent with tools can create a larger consequence because its context may be connected to email, files, databases, APIs, browsers, code execution or administrative workflows.
A 2026 systematization of prompt-injection attacks on agentic coding assistants highlights the expanded attack surface created by external tools, file systems and shell access. The same principle applies beyond coding agents: every capability attached to the model can become part of the blast radius if the model is manipulated.
That is why agent security should treat model behavior and system authorization as separate layers. The model can propose an action. A trusted execution layer should decide whether the action is allowed.
Map the attack path: content to context to tool
Direct prompt injection comes from the user-facing input. Indirect prompt injection arrives through content the agent is asked to process. OWASP lists examples such as webpages, documents, emails, database records and API responses. For an agent, retrieval results and tool responses belong in the same threat model: they are data from outside the trusted instruction boundary.
| Stage | What can be untrusted | Control that limits impact |
|---|---|---|
| Content ingestion | Email, webpage, document, retrieved record, API/tool response | Classify source trust, normalize and inspect content, restrict which sources are accepted |
| Model context | Instructions embedded inside otherwise legitimate data | Separate trusted instructions from external content and label trust boundaries |
| Tool selection | Model proposes a tool because of injected content | Allowlisted tools, task-specific scopes and server-side authorization |
| Tool arguments | Unexpected recipient, file path, query, URL or resource | Schema validation, resource constraints and policy checks |
| Side effect | Send, delete, publish, transfer, modify, execute | Independent approval for high-consequence actions |
| Persistence | Memory or long-lived state records malicious content | Validated memory writes, user/session isolation and review |
The important point is that filtering at the first stage is only one layer. If suspicious text survives content screening, permission and approval controls should still stop an unauthorized side effect.
Put authorization at the tool boundary
Least privilege is one of the strongest controls because it limits what a compromised decision layer can do. OWASP recommends giving agents only the tools and permissions required for the task. That means separating read from write access, scoping credentials to specific resources, and avoiding wildcard permissions.
A summarization agent does not need permission to send email. A research agent that reads a document repository usually does not need permission to delete files. A support agent may need to draft a refund recommendation without having authority to issue the refund automatically.
| Capability | Safer default | Stronger control when enabled |
|---|---|---|
| Read data | Only task-relevant sources | Per-user/resource authorization and data classification |
| Write or modify | Disabled unless required | Restricted fields/resources plus validation |
| Send externally | Draft only | Recipient/domain policy and user approval |
| Delete or revoke | Disabled | Explicit approval and recoverable operation where possible |
| Administrative action | Separate privileged path | Strong identity check, narrow scope and independent authorization |
| Code/system execution | Constrained environment | Filesystem, network, credential and runtime limits |
OWASP’s prompt-injection prevention guidance also recommends tool-specific permission checks and action-specific approval. The key design rule is that the model should not be able to grant itself more authority by producing persuasive text.
Require approval for consequential actions
Human-in-the-loop is useful only when the approval is enforced by the execution system. A prompt that tells the model to “ask before doing anything sensitive” is not an authorization boundary if the same model can decide that the action is not sensitive.
For consequential operations, the approval should show the actual proposed action, target and important arguments. A user approving “send this email to vendor@example.com” should not silently authorize a later change to a different recipient. The executor should verify that the approved action is the same action that runs.
Approval is especially valuable for external messages, destructive changes, permission modifications, publication, sensitive-data disclosure and other actions that are difficult to reverse. It is an extra layer, not a replacement for least privilege.
Validate tool calls, arguments and outputs
Tool calls should be treated like API requests from an untrusted decision-maker. Validate the operation against the user’s authority and current session. Validate parameters against a schema. Restrict paths, domains, record IDs and resource types to what the task actually needs.
Model output also needs destination-specific validation. Text that is safe to display in a chat window is not automatically safe to execute as a database query, shell command, HTML fragment or external request. OWASP recommends treating model output as untrusted at downstream use rather than assuming a successful model response is safe.
These checks are more reliable than keyword matching alone because they enforce what the system is allowed to do, not merely what the model appears to be talking about.
Treat tool descriptions and responses as untrusted
Tool integration creates two additional instruction channels: the description that tells the model what a tool does, and the response returned after a tool call. OWASP describes MCP tool poisoning as an indirect prompt-injection path in which a malicious tool response can place hidden instructions into the agent’s context.
For external tool servers, review the server before connection, allowlist approved integrations, constrain response formats where practical, and keep high-privilege internal tools separated from untrusted tool contexts. A tool response should provide data; it should not automatically become authority to call a more privileged tool.
Structured responses can help reduce ambiguity, but they do not replace authorization. A perfectly valid JSON object can still request an operation the current user is not allowed to perform.
Treat memory as a security boundary
Prompt injection can become more serious when malicious content is persisted. OWASP lists memory poisoning as an agent-security risk because malicious data stored in memory can influence later sessions or other users.
Memory writes therefore deserve their own policy. Decide which fields can be stored, which sources are eligible to create durable memory, how users or organizations are isolated, and when a memory item should expire or require review. Sensitive credentials and secrets should not be stored simply because the model decides they may be useful later.
AiTechJournal’s report on persistent AI memory injection is a useful concrete example of why the persistence layer changes the threat model. The broader design lesson is to treat memory as state with security consequences, not as harmless conversation history.
Constrain the runtime, not just the prompt
Agents that can execute code or interact with local systems need a separate containment layer. Google Cloud recommends running agents in a constrained environment when possible when addressing indirect prompt-injection risk.
Useful controls include restricted filesystem roots, limited network destinations, scoped credentials, resource limits and separation between untrusted workloads and privileged services. If an agent only needs to transform a file in a temporary workspace, it should not inherit unrestricted access to the user’s home directory, browser credentials or internal network.
AiTechJournal’s coverage of Microsoft Execution Containers for AI-agent isolation illustrates the same architectural principle: enforcement outside the model provides a boundary the model cannot simply talk its way around.
Monitor behavior and red-team the full workflow
Monitoring should focus on actions and trust-boundary transitions, not only on suspicious words in prompts. Log security-relevant metadata such as tool selected, authorization result, target resource, approval decision, policy block and memory write. Avoid logging credentials or unnecessary sensitive prompt content.
Red-team the complete workflow with harmless, instrumented targets. Test direct injection in user input, indirect instructions in documents and retrieved content, unexpected tool responses, attempts to write persistent memory, requests to cross resource boundaries, and attempts to change an approved action before execution.
Run these tests again after changing the model, system prompt, retrieval pipeline, tool set, memory implementation or provider. A control that worked for one architecture can become irrelevant when the data path changes.
Practical deployment checklist
- Inventory every tool and classify it as read, write, external-send, destructive, administrative or execution-capable.
- Remove tools and permissions the agent does not need for its specific role.
- Enforce user/resource authorization outside the model for every tool call.
- Validate tool arguments and restrict destinations, paths and resource IDs.
- Require independent approval for consequential actions and bind the approval to the exact action.
- Treat web content, email, documents, retrieval results, tool responses and memory inputs as untrusted.
- Separate high-privilege tools from untrusted external tool contexts.
- Control memory writes, isolate users and organizations, and make durable state reviewable.
- Run code-capable agents in a constrained environment with limited filesystem, network and credential access.
- Log authorization decisions and sensitive side effects without storing unnecessary secrets.
- Maintain a kill switch or revocation path for agent credentials and integrations.
- Repeat adversarial tests after meaningful model, prompt, tool, memory or retrieval changes.
Prompt injection remains difficult because the model consumes instructions and data in the same overall reasoning context. The strongest practical strategy is therefore to reduce what an injected instruction can accomplish. When permissions, approvals, tool validation, memory controls and runtime boundaries are enforced outside the model, prompt injection becomes a contained security event rather than an automatic path to privileged action.