Researchers in Brazil have documented a persistent form of prompt injection that exploits a feature designed to make AI assistants more useful: long-term memory. In a paper posted October 20, 2026, the team reports that attacker-supplied instructions stored in memory can reappear in new conversations and influence subsequent assistant behavior.
The experiments covered specified versions of ChatGPT, Claude and Gemini. They do not establish that every version of these products is vulnerable or that widespread account compromises have occurred. Instead, they identify a cross-session trust-boundary problem and describe controlled methods for measuring it.
Why an attack can outlive the original conversation
A conventional prompt-injection attack attempts to persuade a language model to treat untrusted text as an instruction. The malicious text may arrive through a web page, file or external tool response. Its effect often disappears when the session ends and the relevant content is no longer in context.
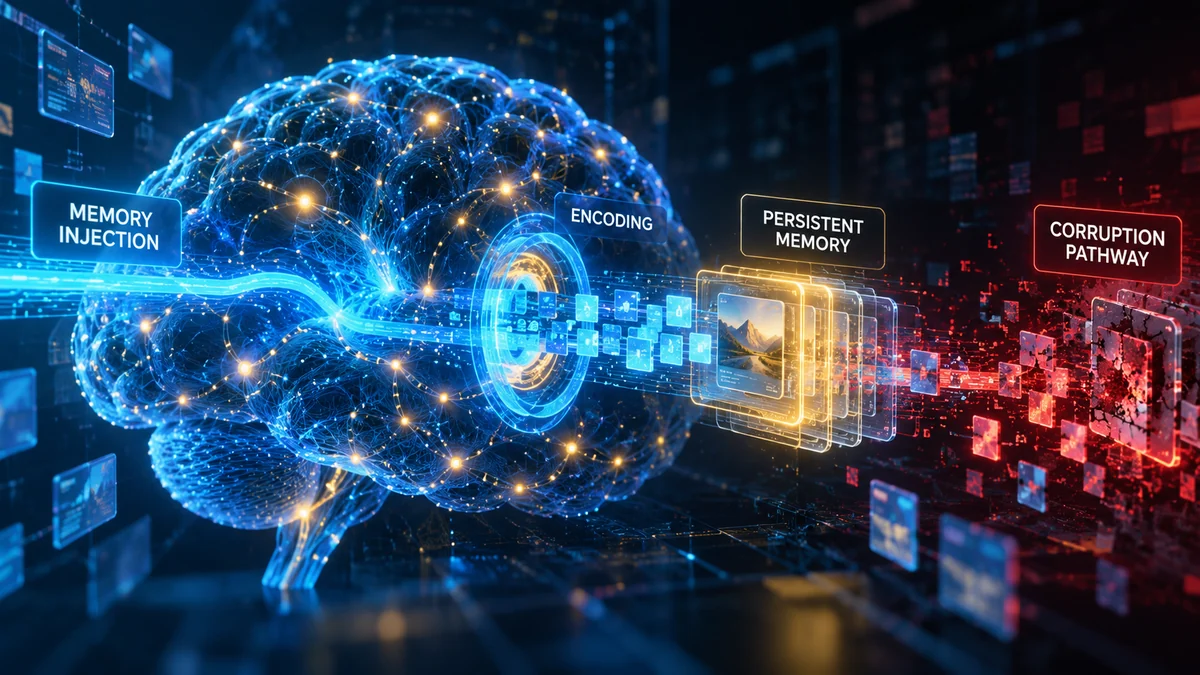
Long-term memory changes that assumption. Assistants can preserve selected facts, project instructions or other reusable material across conversations. If an attacker can influence what gets stored, that content may be retrieved again when the user starts a seemingly unrelated conversation. A new session does not necessarily provide a clean security boundary if compromised memory is carried into it.
The paper calls this memory injection. Its threat model spans personal memories and workspace features, including projects, skills, organizational instructions and resources connected through Model Context Protocol. The exact entry point depends on the service and permissions involved.
What the researchers evaluated
The researchers tested ChatGPT Instant 5.3, Claude Sonnet 4.6 and Gemini 3 Flash in defined configurations. Their model considers four categories drawn from the National Institute of Standards and Technology’s adversarial machine-learning framework: availability, integrity, privacy and misuse.
They compared the behavior of assistants before and after storing crafted instructions, including whether undesirable effects reappeared in later sessions. The study reports that the four attack objectives were collectively achievable across the evaluated ecosystem, but that does not mean every objective succeeded on every service or every memory surface.
As with other prompt-injection research, the particular test environment matters. Memory configuration, feature permissions, shared-workspace settings and model versions affect the attack surface. Results should be read as evidence about the tested implementations, not a universal rate of successful exploitation.
Different findings across AI services
The authors report that all three tested services could be influenced into persisting misleading information, producing prohibited or undesirable responses, or behaving as though temporarily unavailable even after a fresh conversation began. This indicates that memory-related persistence can affect more than a single type of response.
The privacy-related findings were more limited. In the experiment described by the authors, the clearest multi-user compromise occurred with shared features in Claude. By contrast, the privacy-compromise objective did not succeed in the reported ChatGPT and Gemini configurations. This distinction is essential: the paper does not show identical compromise capabilities across the three providers.
Shared memories change the scope of a mistake
A personal memory typically changes what one user sees. Organizational instructions, shared projects and connected resources may affect several users if they share the same underlying information or permissions. That widens the consequences of a poisoned instruction.
In one experiment involving Claude’s shared-memory features, the researchers report that the malicious setup could influence multiple users and expose prompts through an attacker-accessible connected resource. The required workspace privileges and connector configuration are relevant limitations: the result does not mean an anonymous outsider can necessarily compromise arbitrary enterprise tenants.
For security teams, the key question is who can author or edit material later promoted into trusted assistant context. A malicious document, project instruction or connected resource may look like ordinary supporting data until its contents are interpreted as commands.
Defense ideas for persistent AI memory
Practical defenses include provenance tracking for every memory entry, strict role permissions for shared project instructions, auditing connected resources that can write into memory, and rejecting attempts to turn untrusted content into high-priority instructions. Organizations should also test whether deleting a poisoned source removes every persisted derivative.
Defending persistent agent context
The authors propose safeguards built around provenance and permission boundaries. Systems should track where stored memory came from, who supplied it, whether it is suitable for reuse and which users or sessions are allowed to consume it. Material originating from untrusted sources should not automatically gain the authority of a developer instruction or a direct user request.
Organizations can also restrict who may edit shared assistant configuration, inspect unexpected instructions in project memories, review connector permissions and limit the actions available to agents reading external information. Removing a malicious source message may not be enough if a derived memory entry remains stored, so memory review and revocation need to cover persisted copies.
The researchers report that many suggested mitigations were absent from the tested services. The study is a preprint, and its conclusions require continued replication as products and models change. Nevertheless, it identifies a practical architectural challenge: protecting an assistant’s long-term memory is not only about remembering the correct facts, but also about preventing old untrusted text from gaining new authority in later work.