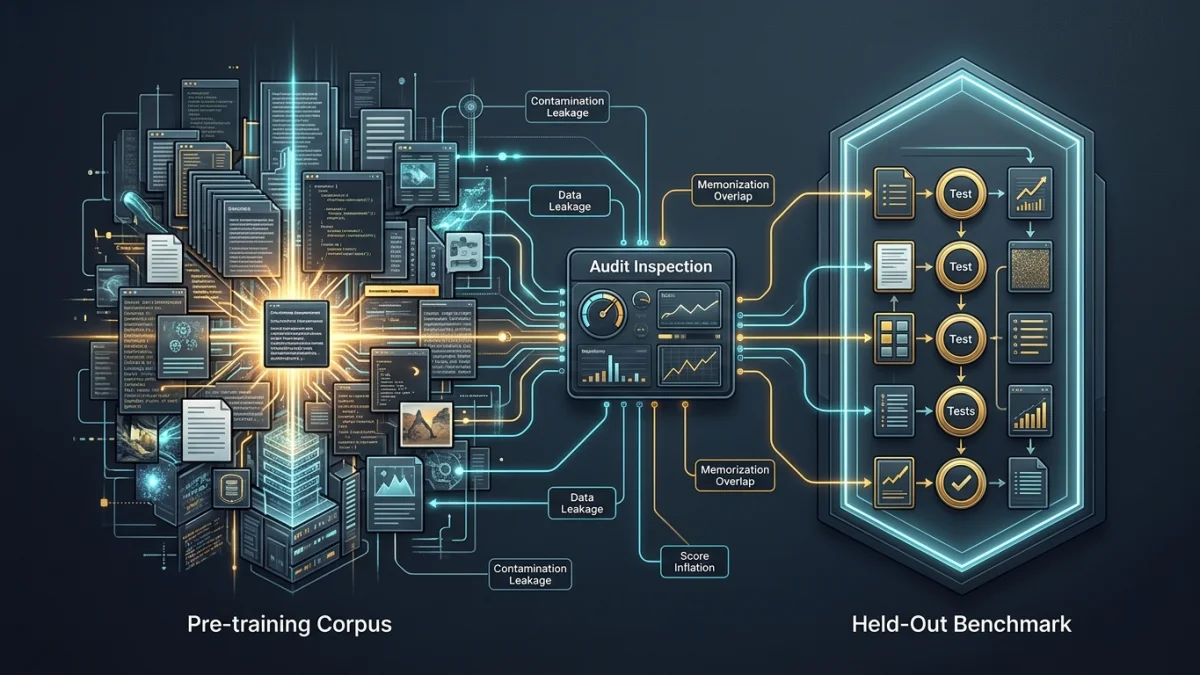
A suspiciously high benchmark score is not enough to prove contamination. Benchmark contamination means evaluation examples were exposed to the model during training or another pre-evaluation stage, creating a risk that the score reflects prior exposure rather than performance on genuinely unseen data. The practical response is to combine several signals: training-data overlap where available, memorization behavior, release dates and training cutoffs, performance on fresh or perturbed tests, and the details of the evaluation protocol.
The key is calibration. A single clue can justify more investigation, but the strongest conclusions come from multiple independent lines of evidence.
What benchmark contamination actually means
An ACL/EMNLP paper on LLM data contamination describes the clearest case as a model being trained on a benchmark’s test split and then evaluated on that same benchmark. The core problem is not simply that a benchmark exists on the public web. It is that evaluation data intended to measure generalization may already be part of what the model learned from.
This should be separated from ordinary benchmark overfitting. A team can repeatedly tune prompts, thresholds or model choices against a public benchmark without the benchmark examples appearing in pretraining. That can still make the benchmark less representative, but it is a different failure mode from training-data contamination.
It is also useful to separate three questions:
- Exposure: Did benchmark content appear in training or another optimization stage?
- Memorization: Can the model reproduce benchmark-specific content in a way that suggests prior exposure?
- Score inflation: Did that exposure materially improve the measured benchmark result?
Those questions are related, but they are not interchangeable.
Why a high benchmark score can become misleading
The ACL/EMNLP paper argues that contamination can overestimate a model’s performance on a target benchmark relative to a non-contaminated model. That matters because benchmarks are often used for ranking models, selecting systems for deployment, or supporting claims about a capability.
If a model has already seen the evaluation examples, a strong score may not transfer to new examples from the same task. A contaminated result can therefore make one model look better than another for the wrong reason.
The practical question is not whether the model “cheated” in a human sense. Large-scale pretraining pipelines can ingest public material without a model developer intentionally targeting a benchmark. What matters is whether the evaluation remains a valid measurement of performance on unseen data.
Why proving a benchmark is clean is difficult
The same ACL paper notes that the extent of contamination is difficult to measure. Modern pretraining corpora can be enormous, continuously assembled from many sources, or unavailable to outside evaluators. Even when a developer documents major data sources, an external researcher may not have a searchable copy of the exact training set.
This creates an asymmetry. Finding a benchmark example in a known training corpus can be strong evidence of exposure. Failing to find it does not necessarily prove the model never saw a duplicate, paraphrase, translated copy, answer explanation or related derivative elsewhere.
That is why contamination analysis should report confidence rather than forcing every benchmark into a binary clean/contaminated label.
Use an evidence ladder, not a yes-or-no label
A useful way to review a suspicious score is to rank evidence by strength.
| Evidence | What it suggests | What it does not prove |
|---|---|---|
| Benchmark is old and widely mirrored online | Exposure is plausible | That the model actually trained on it |
| Exact or near-duplicate examples found in training data | Direct exposure for those examples | How much the final score was inflated |
| Model reproduces benchmark-specific wording or answers | Possible memorization or prior exposure | That all correct answers are memorized |
| Performance drops on fresh/post-cutoff versions | Original benchmark may be less representative | Contamination by itself; task distribution may also change |
| Controlled experiments show more exposure produces higher scores | Causal evidence that contamination affects measurement | The exact effect size in a different model or benchmark |
The last distinction is important. Evidence that contamination can inflate scores does not supply a universal correction factor for every benchmark.
Use multiple contamination checks
No single detector works in every situation. Use the checks that match the evidence you can access.
Search the training corpus when you have it
Exact matches, normalized text matches and n-gram overlap are direct checks when the relevant training data are available. They can identify obvious leakage and near-duplicates. They are much less decisive when the corpus is incomplete or when benchmark content has been paraphrased, reformatted or embedded inside explanations.
Probe for memorization
Tests that ask a model to complete benchmark-specific text, reconstruct labels or reproduce distinctive phrasing can provide evidence of prior exposure. But memorization should be interpreted alongside other signals. A model can know common task patterns without memorizing a particular test item, and prior exposure does not mean every correct answer is pure recall.
Use time as a natural boundary
If a model has a documented training cutoff, problems or documents released after that date are less likely to have appeared in its earlier training corpus. Comparing similar pre-cutoff and post-cutoff examples can therefore provide useful evidence, especially when difficulty is controlled as carefully as possible.
Rephrase or perturb the evaluation
Semantically equivalent variants can test whether performance depends unusually strongly on the public benchmark’s exact form. Reordering answer choices, changing names or surface wording, and constructing equivalent new items can reveal brittleness. A drop is a diagnostic signal, not automatic proof of contamination, because formatting changes can affect models for other reasons too.
Use fresh or private test sets
New examples, withheld labels and private evaluation sets reduce the opportunity for prior exposure. They are especially useful when the underlying task can be regenerated or updated over time.
Look for a dose-response pattern, not one suspicious score
A controlled NeurIPS study on generative benchmarks deliberately varied the amount of contaminated test data in pretraining. The authors reported that benchmark performance increased with contamination and that the effect also varied with model size.
This kind of experiment is stronger than simply observing that a model scored well on an old benchmark because the amount of exposure is manipulated directly. It helps establish that contamination can change the measured result.
The study also shows why simple rules are risky. The effect was not described as a fixed bonus that can be subtracted from every score. Evaluation format and generation settings matter.
Do not treat memorization as a one-number detector
The same NeurIPS work reports a close relationship between generative performance and test-set memorization, while also finding that sampling temperature and solution length changed the observed contamination effect.
That means an evaluator should record the generation protocol when testing for contamination. A memorization probe run with one sampling configuration is not automatically comparable with a benchmark run under another. Longer solutions may also behave differently from short-answer tasks.
Use memorization as one component of an evidence package rather than as a universal threshold that declares a model contaminated.
Design evaluations that are harder to contaminate
Contamination is easier to manage when benchmark design starts with provenance and refreshability.
| Design practice | Why it helps |
|---|---|
| Record benchmark release dates and versions | Makes cutoff comparisons and later audits possible |
| Keep final labels or some test items private | Reduces direct availability in public training corpora |
| Refresh examples periodically | Prevents one static public set from becoming the permanent target |
| Use post-cutoff or newly collected data | Creates a cleaner temporal boundary for older model training |
| Maintain provenance for each item | Supports overlap searches and later contamination investigations |
| Version the evaluation protocol | Separates score changes caused by model capability from changed prompts or scoring |
For system-level evaluations, the same discipline applies beyond base-model benchmarks. AiTechJournal’s guide to evaluating RAG systems similarly separates different quality dimensions and relies on repeatable test sets rather than one aggregate score.
A practical checklist for suspicious benchmark scores
Before trusting a surprising leaderboard result, ask:
- When was the benchmark released, and how widely was it published or mirrored?
- What is the model’s documented training cutoff, if one is available?
- Was the benchmark used during pretraining, fine-tuning, model selection, prompt tuning or evaluation development?
- Can the evaluator search any portion of the relevant training corpus for exact or near-duplicate items?
- Does the model show benchmark-specific memorization beyond what the task itself requires?
- Does performance hold on fresh, private, post-cutoff or independently generated examples?
- Does the score remain stable under reasonable rephrasing or perturbation?
- Were generation settings, prompts, number of samples and scoring rules held constant?
- Are contamination suspicions reported separately from proven exposure?
- Would the deployment decision change if the public benchmark score were excluded?
A trustworthy benchmark result is not simply a high number. It is a measurement with enough provenance and independent checks to support the claim being made. When training data are opaque, the safest approach is to combine overlap evidence, memorization tests, temporal boundaries and fresh evaluation rather than pretending any single detector can certify that a benchmark is perfectly clean.